Wednesday, September 21, 2011

Cow Says Moo for Android - Teach Your Kids Farm Animal Sounds

Cow Says Moo Feature Image

James, my partner in Mobile Magic Developers, and I have a handful of Android applications under our belts now. We loved working on Chinese Whispers, an idea my wife gave me for a new twist on The Telephone Game. James wrote an immensely handy application for getting your WiFi Passwords from your phone.

I wrote the Chuck Norris Fact of the Day Widget and the Jane Austen Fact of the Day Widget, and James wrote a really nice widget that shows you your last few installed applications called Latest Apps.

But… Then we Wrote Cow Says Moo

Cow Says Moo is definitely my favorite so far. Many of my friends and family are having babies now and my wife and I have one on the way. I noticed that kids are growing more and more interested in technology and are remarkably capable with it. My niece loved playing with my Motorola Xoom and I loved the way her face lights up when she touches the screen and something happens. That's where we got the idea for Cow Says Moo.

Cow Says Moo is an educational game to teach young kids and toddlers about farm animals and the sounds they make. Each picture is hand illustrated by Emily Upchurch Robinson and when pressed plays farm animal sounds. You can use the front facing camera on your device (or the rear camera if you prefer) to record video and sound while your child interacts with your mobile device or while you simply delight him or her with the sounds. You can use the built in media gallery to share your videos with friends and family. You'll be surprised how much fun you'll have playing Cow Says Moo with your kids and you'll get a lot of cute video footage like I did "User Acceptance Testing", i.e., playing Cow Says Moo with my godson AJ.

Check out Cow Says Moo, and as always, feel free to contact us with any comments or bugs.

Friday, September 2, 2011

7-bit Encoding with BinaryWriter in .Net

JetBrains dotPeek LogoAt work this week, I had the need to serialize objects and encrypt them while trying to keep the smallest data footprint I could. I figured the easiest thing to do would be to binary serialize them with the BinaryFormatter. It was, indeed, the easiest thing to do; however, the BinaryFormatter seems to come with a fair amount of overhead. By the time the BinaryFormatter was finished listing all of the necessary assembly-qualified type names, the 60 bytes of data I wanted to preserve were more than a kilobyte!

I needed another way so I extended BinaryWriter (mostly to get it to serialize the types I needed it to) and now my 60 bytes take 68 bytes to serialize. In the process of writing this class, I looked through the disassembled BinaryWriter using JetBrains's dotPeek and found this little gem (Write7BitEncodedInt(int)) and decided it'd make a great dotPeek of the Week:
protected void Write7BitEncodedInt(int value)
{
  uint num = (uint) value;

  while (num >= 128U)
  {
    this.Write((byte) (num | 128U));
    num >>= 7;
  }

  this.Write((byte) num);
}
This is how the BinaryWriter.Write(string) encodes the length of the string. Thus, if you have a string with fewer than 128 characters, it only takes one byte to encode the length. In my implementation, I used this to specify the length of collections too. In fact, when writing a 32 bit signed integer, you should be able to save space for all positive numbers less than 2 ^ 22 and break even (require four bytes) for 2 ^ 29. Encoding an Int32 that is greater than or equal to 2 ^29 will require five bytes. Thus, if your integers tend to be smaller than 536,870,912, you'll probably save space encoding this way. A similar function could be used for a long where all positive values less than 2 ^ 57 will result in at least breaking even.

Here's how it works:
  1. Convert the number to an unsigned int so you can do arithmetic on positive numbers (after all, you're just writing bits)
  2. While the converted value is greater than or equal to 128 (i.e., 8 bits)
    1. Write low 7 bits and put a 1 in the high bit (to indicate to the decoder more bytes are coming)
    2. Shift the 7 bits you just wrote off the number
  3. When the loop finishes, there will be 7 or fewer bits to write so write them
I think this is really clever and very easy. Reading the data back is a smidgen more complicated (Read7BitEncodedInt()):
protected internal int Read7BitEncodedInt()
{
  // some names have been changed to protect the readability
  int returnValue = 0;
  int bitIndex = 0;

  while (bitIndex != 35)
  {
    byte currentByte = this.ReadByte();
    returnValue |= ((int) currentByte & (int) sbyte.MaxValue) << bitIndex;
    bitIndex += 7;

    if (((int) currentByte & 128) == 0)
      return returnValue;
  }

  throw new FormatException(Environment.GetResourceString("Format_Bad7BitInt32"));
}
Here's how this works:
  1. Set up an int to accumulate your data as you read them
  2. Set up a place to keep track of which 7-bit block you're reading
  3. While your bit index is less than 35 (i.e., you've read no more than 5 bytes comprising 1 "more bytes" indicator and 7 data bits)
    1. Read a byte
    2. Take the byte you just read and logical conjuction (bitwise and) it with sbyte.MaxValue (127 or in binary 0111 1111)
    3. Left shift those 7 bits to the position in which they belong
    4. Use a logical disjunction (bitwise or) to write those seven bits into your accumulator int
    5. Add 7 to your bit index for the next 7 bits you read
    6. If the current byte you read does not have a 1 in its most significant bit (i.e, byte & 1000 0000 == 0)
      1. There are no more bytes to read so just return the current accumulator value
  4. If you get to this point, you've read a 6th of 5 bytes and it's time to let the user know there was a formatting problem

Thursday, August 25, 2011

.Net GetHashcode Functions

JetBrains dotPeek LogoLast week, I wrote a post about a .Net method to combine hashcodes. In the process of designing that method, I looked into dozens of .Net's GetHashcode implementations.

If you'd like to know the principles of hashcodes, take a look at the aforementioned article. This one is part of the dotPeek of the Week series so I'll just be sharing the insight I got from the framework's implementations here.

First, some really basic ones:
// from Int32
public override int GetHashCode()
{
  return this;
}

// from Int16
public override int GetHashCode()
{
  return (int) (ushort) this | (int) this << 16;
}

// from Int64
public override int GetHashCode()
{
  return (int) this ^ (int) (this >> 32);
}

The Int32 implementation easily meets the hashcode requirements by returning itself. The Int16 copies itself to the top half of the Int32 and returns that. The Int64 takes the bottom half of itself and XORs it with the top half.

This XOR is the first valuable piece of information. If you look at the logical functions, the XOR produces the best bit twiddling for hashing. Basically, the XOR produces a relatively even distribution of bits as opposed to the OR and the AND operations which will be biased 3 to 1 in one direction or the other.

Some more complicated implementations:
// from String
public override unsafe int GetHashCode()
{
  fixed (char* chPtr = this)
  {
    int num1 = 352654597;
    int num2 = num1;
    int* numPtr = (int*) chPtr;
    int length = this.Length;
    while (length > 0)
    {
      num1 = (num1 << 5) + num1 + (num1 >> 27) ^ *numPtr;
      if (length > 2)
      {
        num2 = (num2 << 5) + num2 + (num2 >> 27) ^ numPtr[1];
        numPtr += 2;
        length -= 4;
      }
      else
        break;
    }
    return num1 + num2 * 1566083941;
  }
}

// from Tuple<>
internal static int CombineHashCodes(int h1, int h2)
{
  return (h1 << 5) + h1 ^ h2;
}
These two methods have some really good information in them. The String.GetHashcode implementation has what's called a rolling hash. It loops through the characters, does a barrel shift by 5, and then XORs with the next character.

While I liked this, I preferred the simplicity of the Bernstein Hash. The main component of the Bernstein Hash is the (i << 5) + i. i << 5 == i * 32 (except that bit shifting is much faster than multiplying).

Thus, i << 5 + i == 32i + i == 33i. The Bernstein Hash just takes the current hash value, multiplies it by 33, and XORs in the new value.

I didn't use 33 in my hash function because I feel like using prime numbers is healthy. Thus, instead of adding I subtract so my hashcode method is (hash << 5) - hash ^ value (or 31 * hash ^ value). This, by the way, is the way Java tends to do it.

Here are some interesting ones from System.Drawing:
// from Size
public override int GetHashCode()
{
  return this.width ^ this.height;
}

// from Rectangle
public override int GetHashCode()
{
  return this.X ^ (this.Y << 13 | (int) ((uint) this.Y >> 19)) ^ (this.Width << 26 | (int) ((uint) this.Width >> 6)) ^ (this.Height << 7 | (int) ((uint) this.Height >> 25));
}

// from Point
public override int GetHashCode()
{
  return this.x ^ this.y;
}

Thursday, August 18, 2011

.Net Method to Combine Hash Codes

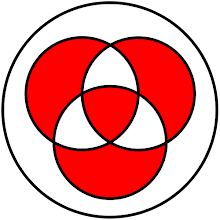
XOR Venn DiagramA while back I developed a helper method that I've been using to aid me in computing good hash values from sets of properties for an object. I was writing a dotPeek of the Week entry about .Net GetHashcode implementations and I decided to spruce up my implementation and post it on my blog.

I know It's pretty uncommon that you need to override the Equals method, but when you do, you have to take particular care in considering overriding the GetHashCode method as well. To make this a little easier, I developed a method I call CombineHashCodes().

Using CombineHashCodes, I can easily compute a well randomized composite hash code based on several parameters from an object. This curtails a lot of the work involved when dealing with objects that have complicated .Equals overrides.

Microsoft's documentation on Object.GetHashCode() lists the following rules:
A hash function must have the following properties:

If two objects compare as equal, the GetHashCode method for each object must return the same value. However, if two objects do not compare as equal, the GetHashCode methods for the two object do not have to return different values.

The GetHashCode method for an object must consistently return the same hash code as long as there is no modification to the object state that determines the return value of the object's Equals method. Note that this is true only for the current execution of an application, and that a different hash code can be returned if the application is run again.

For the best performance, a hash function must generate a random distribution for all input.

Thus, if you override the .Equals method such that it's no longer doing the default reference equality, you probably need to change your GetHashCode implementation. I've found this is usually a very simple task. I whipped up a quick example in LINQPad:
void Main()
{
 var lauren1 = new Person { FirstName = "Lauren" };
 var lauren2 = new Person { FirstName = "Lauren" };
 
 Console.WriteLine(lauren1.Equals(lauren2));
 Console.WriteLine("{0}.GetHashCode() = {1}", "lauren1", lauren1.GetHashCode());
 Console.WriteLine("{0}.GetHashCode() = {1}", "lauren2", lauren2.GetHashCode());
 
 if (lauren1.Equals(lauren2) && lauren1.GetHashCode() != lauren2.GetHashCode())
  Console.WriteLine("This is bad.  This is very bad.");
}

public class Person
{
   public string FirstName { get; set; }
}

/*
False
lauren1.GetHashCode() = 47858386
lauren2.GetHashCode() = 20006478
*/

As one would expect, lauren1 does not equal lauren2 and neither do the hashcodes; however, if we were to override the .Equals method on the Person object to compare just the first name, we'll find that lauren1 and lauren2 will be equal but will have different hashcodes! This violates the first rule of GetHashCode Club. Here's an example:
public class Person
{
   public string FirstName { get; set; }
  
   public override bool Equals (object obj)
   {
  var otherPerson = obj as Person;
  
  if (otherPerson == null)
   return false;
   
  return String.Compare(this.FirstName, otherPerson.FirstName, StringComparison.OrdinalIgnoreCase) == 0;
 }
}

/*
True
lauren1.GetHashCode() = 33193253
lauren2.GetHashCode() = 37386806
This is bad.  This is very bad.
*/

That's why we override GetHashCode as well and something like this will work:
public override int GetHashCode()
{
 return FirstName.GetHashCode();
}

/*
True
lauren1.GetHashCode() = 2962686
lauren2.GetHashCode() = 2962686
*/

That's all well and good (except the .Equals() does a case insensitive compare so "Lauren" and "lauren" will be equal but will result in different hash codes unless you do something like return FirstName.ToLower().GetHashCode(). Why'd I leave that error in the post just to parenthetically correct it . . . because I think it's a good demonstration of how easy it is to screw this up :)). Consider what happens when you end up with a more complex class that looks like this:
public class Person
{
   public string FirstName { get; set; }
 public string LastName { get; set; }
 public DateTime BirthDate { get; set; }
  
   public override bool Equals (object obj)
   {
  var otherPerson = obj as Person;
  
  if (otherPerson == null)
   return false;
   
  return String.Compare(FirstName, otherPerson.FirstName, StringComparison.OrdinalIgnoreCase) == 0
   && String.Compare(LastName, otherPerson.LastName, StringComparison.OrdinalIgnoreCase) == 0
   && BirthDate.Equals(otherPerson.BirthDate);
 }
}

You could leave the GetHashCode function the way it was previously, but then all Lauren's will be lumped in the same bucket together which violates the third rule about a random distribution. I've seen people combat this problem by concatenating the string values of the equals fields delimited by some extremely unlikely string and getting the hash code of that.

I felt like that was not really the best way to do it in case someone decides a colon is a good character in a first name or something worse.

Thus, I wrote something like this (which has recently been modified to what you see now based on my explorations for my dotPeek of the Week series). This is CombineHashCodes:
public static class HashCodeHelper
{
 public static int CombineHashCodes(params object[] args)
 {
  return CombineHashCodes(EqualityComparer<object>.Default, args);
 }

 public static int CombineHashCodes(IEqualityComparer comparer, params object[] args)
 {
  if (args == null) throw new ArgumentNullException("args");
  if (args.Length == 0) throw new ArgumentException("args");

  int hashcode = 0;

  unchecked
  {
   foreach (var arg in args)
    hashcode = (hashcode << 5) - hashcode ^ comparer.GetHashCode(arg);
  }

  return hashcode;
 }
}

With this method, you can get a nice pseudo-random distribution of hash codes without violating any of the GetHashCode rules as long as you include the values relevant to your Equals method in your call to CombineHashCodes:
public override int GetHashCode()
{
 return HashCodeHelper.CombineHashCodes(FirstName.ToLower(), LastName.ToLower(), BirthDate);
}

/*
True
lauren1.GetHashCode() = -891990792
lauren2.GetHashCode() = -891990792
*/

Monday, August 15, 2011

.Net Optimization for Int32

JetBrains dotPeek LogoAnother entry in the dotPeek of the Week series here. I was digging through some .GetHashcode() implementations (expect that as the next dotPeek of the week) and noticed some interesting implementations of overridden .Equals() methods.

I found this in Int16:
public override bool Equals(object obj)
{
  if (!(obj is short))
    return false;
  else
    return (int) this == (int) (short) obj;
}

public bool Equals(short obj)
{
  return (int) this == (int) obj;
}

So, I checked Byte and sure enough:
public override bool Equals(object obj)
{
  if (!(obj is byte))
    return false;
  else
    return (int) this == (int) (byte) obj;
}

public bool Equals(byte obj)
{
  return (int) this == (int) obj;
}

Can you guess how Char.Equals() is implemented?
public override bool Equals(object obj)
{
  if (!(obj is char))
    return false;
  else
    return (int) this == (int) (char) obj;
}

public bool Equals(char obj)
{
  return (int) this == (int) obj;
}

Even the unsigned int gets cast as a signed int in UInt.Equals(). I was pretty curious, so I looked at some other methods:
public int CompareTo(short value)
{
  return (int) this - (int) value;
}

public int CompareTo(byte value)
{
  return (int) this - (int) value;
}

public int CompareTo(char value)
{
  return (int) this - (int) value;
}

I took note and discussed it with a few friends. It seems to make sense that on a 32 bit operating system, it'd be optimal to work with 32 bit integers. It turns out, even on a 64 bit architecture, .net is optimized for the Int32. I found this gem online:
Best Practices: Optimizing performance with built-in types

The runtime optimizes the performance of 32-bit integer types (Int32 and UInt32), so use those types for counters and other frequently accessed integral variables.

For floating-point operations, Double is the most efficient type because those operations are optimized by hardware.

MCTS Self-Paced Training Kit (Exam 70-536): Microsoft® .NET Framework 2.0—Application Development Foundation

So storing integer values, no matter the ceiling of your expected value, is best done using Int32, particularly if they'll be operated on heavily like an index to a collection or as a counter in an iteration control structure.

Monday, August 8, 2011

Enumerable.Any vs. Enumerable.Count

JetBrains dotPeek LogoThis is the innagural entry into the section of my blog I'm calling "dotPeek of the Week." Workload permitting, it will be a weekly thing where I'll be using JetBrain's dotPeek - a free .NET decompiler to learn more about the .NET framework and share any interesting things I come up with.

In this post, I'll be sharing a little tip I picked up from my friend David Govek.

I can't .Count() the number of times I've seen a line of code like this one:
if (someEnumerable.Count() > 0) 
    doSomething();

I know I've done that myself a handful of times. I think it comes from the pre-.net 3.5 days when you were used to dealing with ICollections that had a .Count property that returned the value of a private field:
public virtual int Count { get { return this._size; } }

When 3.5 came out, the System.Linq.Enumerable class brought with it a Count extension method. I believe it was at that point that people started using .Count() everywhere, including on IEnumerables, which previously didn't have a method for getting the length of the enumerable.

Most of the time, there was very little pain because the engineers over at Microsoft were clever enough to help us out. The first thing they try to do in the .Count extension method is check to see if the IEnumerable is an ICollection. If it is, they just use the Count property which we already know is plenty fast; however, if it's not an ICollection, they have to iterate the Enumerable and count the elements.

Here's what that looks like:
public static int Count<TSource>(this IEnumerable<TSource> source)
{
  if (source == null)
    throw Error.ArgumentNull("source");

  ICollection<TSource> collection1 = source as ICollection<TSource>;
  if (collection1 != null)
    return collection1.Count;

  ICollection collection2 = source as ICollection;
  if (collection2 != null)
    return collection2.Count;

  int num = 0;
  using (IEnumerator enumerator = source.GetEnumerator())
  {
    while (enumerator.MoveNext())
      checked { ++num; }
  }
  return num;
}

If your source is indeed an Enumerable, this is still a fine way to find out how many items there are. The problem is, in the sample code where we're just simply checking to ensure that the Enumerable isn't empty, using .Count can prove costly. Checking that the count is greater than 0 has to enumerate the entire collection and count each item despite the fact that we know it's not empty as soon as we spot the first element.

Fortunately, the clever folks at Microsoft thought of this and also gave us .Any(). This extension method simply gets the Enumerator, calls .MoveNext(), and disposes the Enumerator. MoveNext tries to move to the next element in the collection and returns true until it passes the end of the collection.

Here's what the .Any() method looks like:
public static bool Any(this IEnumerable<TSource> source)
{
  if (source == null)
    throw Error.ArgumentNull("source");

  using (IEnumerator<TSource> enumerator = source.GetEnumerator())
  {
    if (enumerator.MoveNext())
      return true;
  }

  return false;
}

Thus, there's no need to Enumerate the entire Enumerable if you can use .Any() like this refactored code:
if (someEnumerable.Any()) 
    doSomething();

Sunday, August 7, 2011

About dotPeek of the Week

JetBrains dotPeek LogoYesterday, I posted the first post of a series I call the dotPeek of the Week. Why am I using a JetBrains product name in my blog? Well, 'cause I like JetBrains. I love ReSharper for C#, IntelliJ for Android development, and of course, dotPeek for decompiling .Net code.

I also want to support JetBrains by encouraging people to use dotPeek so that they'll keep it free, unlike that other one that got bought by that one company and now is a paid app. Hopefully, I won't have to change the name of this section any time soon :).

The other (and primary) objective of this exercise is to learn more about the .Net framework and how it functions. If I find something interesting, I'll share it here on my blog.

Latest dotPeek of the Weeks